
RTX Neural Texture Compression Is Not Upscaling: How AI Can Trade Texture Memory for GPU Compute
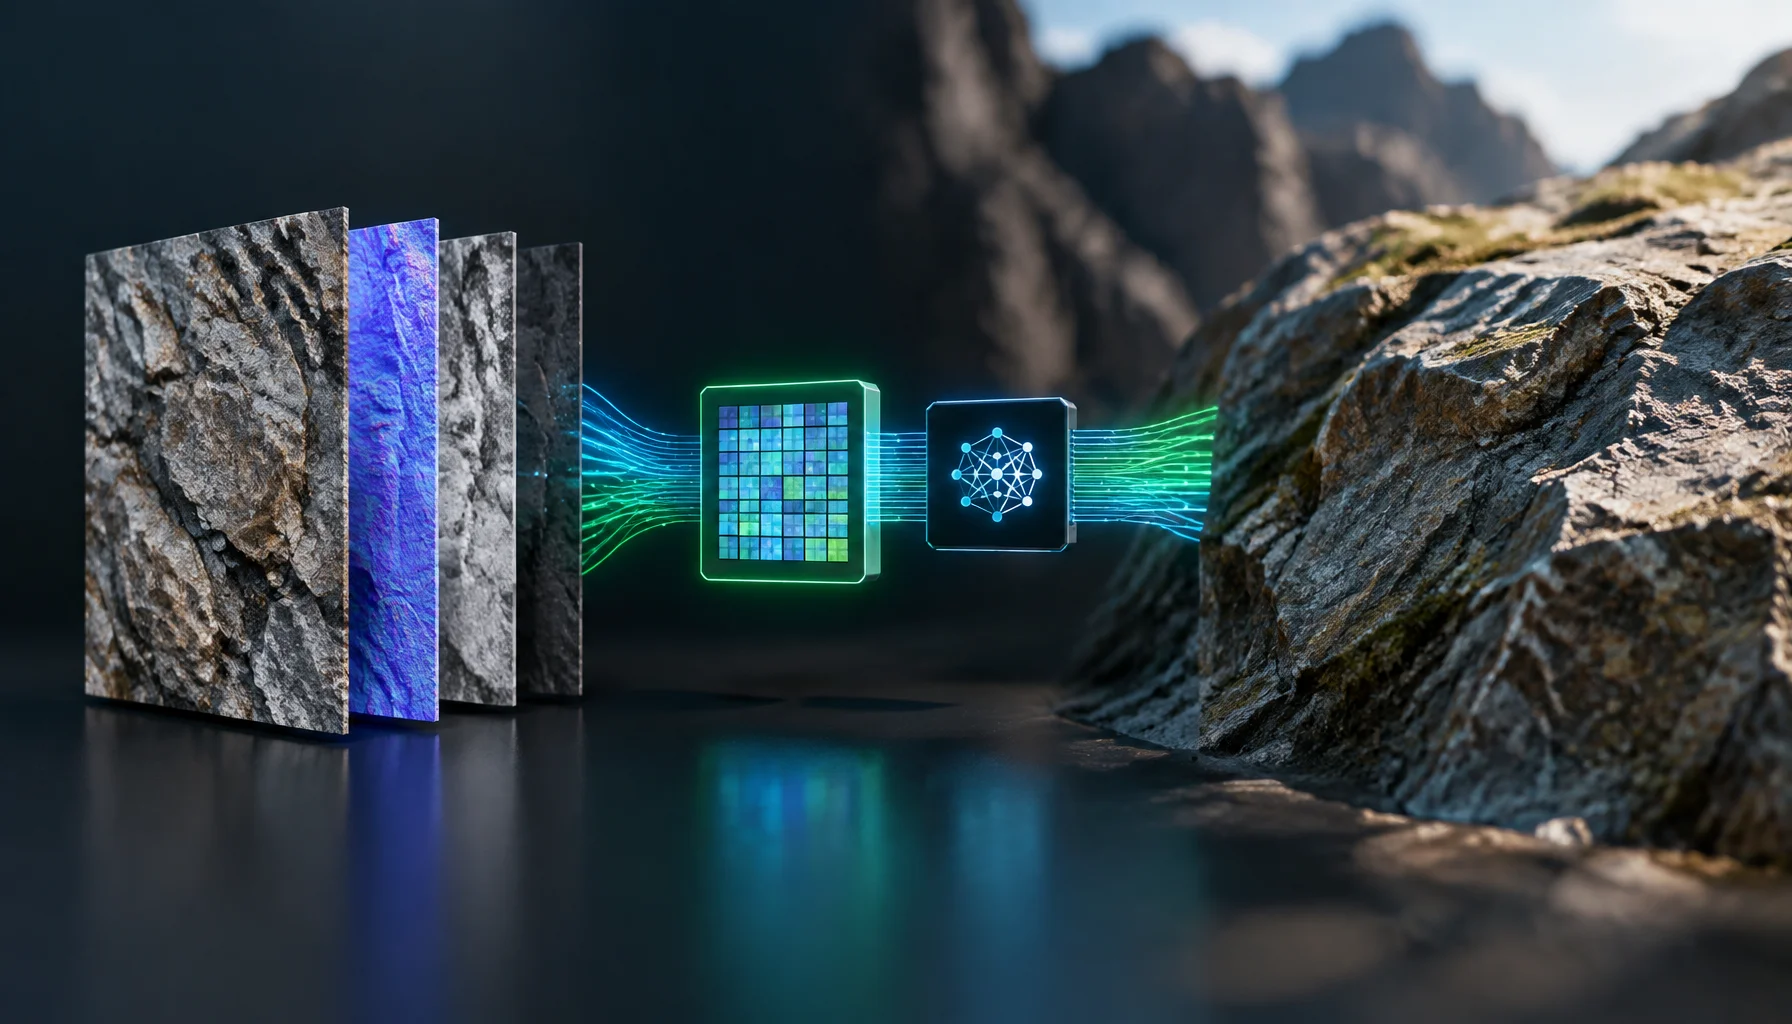
Texture compression normally means storing a smaller version of texture data and expanding it into a conventional GPU format before or during use. NVIDIA RTX Neural Texture Compression changes that model: part of the texture data becomes a small neural representation that can be decoded by the GPU itself.
Why normal texture compression still uses a lot of memory
A modern physically based material rarely consists of one image. A single surface may use albedo, normal, roughness, metalness, ambient occlusion, opacity and other channels.
Traditional GPU block-compression formats such as BC1 through BC7 reduce the cost, but the GPU still ends up storing conventional texture blocks for the material.
As texture resolution and material complexity increase, those channels consume disk space, streaming bandwidth and GPU memory.
What RTX Neural Texture Compression actually stores
NVIDIA's RTXNTC SDK compresses the channels belonging to one material together. The current SDK supports up to 16 texture channels in one NTC texture set.
Instead of keeping only conventional compressed texels, the compression process produces two main things: weights for a small neural decoder and compact latent feature data.
The neural texture pipeline
Why compressing channels together can help
Material channels are often related. A scratch visible in the base color may also appear in the normal or roughness map. A fabric pattern can influence several channels at the same spatial location.
NVIDIA designed NTC to exploit those correlations instead of compressing every texture independently.
That is one reason the technology is described as material-oriented compression rather than merely another image format.
The three NTC runtime modes are the key to understanding the technology
The most important part of RTXNTC is not only how the material is compressed. It is when the game chooses to decompress it.
Inference on Load vs Inference on Sample vs Inference on Feedback
| When neural decoding happens | Runtime texture-memory behavior | Main trade-off | |
|---|---|---|---|
| Inference on Load | |||
| Inference on Sample | |||
| Inference on Feedback |
Inference on Load: neural compression as a storage format
Inference on Load is the easiest mode to understand.
The game stores the material in compact NTC form. When the asset is loaded, the GPU reconstructs the texture data and can transcode it into ordinary BCn texture formats.
After that step, rendering can use normal texture sampling. The important saving is primarily before decompression: packaged game size, download size or asset-streaming bandwidth.
But once the material is fully expanded into conventional textures, its runtime VRAM footprint approaches the conventional representation again.
Inference on Sample: keep the texture neural in VRAM
Inference on Sample is the more radical mode.
Instead of expanding the material into conventional textures before rendering, the shader reads compact latent data and runs the neural decoder when it needs texture values.
NVIDIA's own SDK example compares a 12 MB BCn material representation with a 2.5 MB NTC representation when using Inference on Sample.
The saving is real because the conventional texture data does not need to remain fully resident. But the cost moves somewhere else: the pixel or hit shader now performs neural inference.
Inference on Feedback: decode only what the player actually sees
Inference on Feedback sits between the two extremes.
The renderer tracks which texture tiles are actually requested. Instead of expanding the full material immediately, the system can decode requested tiles in batches and keep a working cache.
Conceptually, this combines neural compression with texture streaming: the system pays the decoding cost only for regions that become relevant.
The current sample implementation is more specialized than the other modes and its support constraints differ, so it should be treated as an integration strategy rather than a universal replacement for ordinary texture streaming.
The Texture Storage–Compute Exchange
The easiest way to understand neural texture compression is as an exchange between resources.
What moves when texture storage becomes neural
| Traditional compressed texture | Neural texture representation | |
|---|---|---|
| Disk/storage | ||
| VRAM | ||
| Sampling cost | ||
| Quality control |
Why special matrix hardware matters
Running a neural network for texture sampling would be too expensive if every multiply had to be handled like ordinary scalar shader work.
RTXNTC therefore benefits from Cooperative Vector and now DirectX 12 Linear Algebra paths that let shaders use GPU matrix-acceleration hardware.
The v0.10.0 beta explicitly added inference through the DirectX 12 Linear Algebra API introduced with Shader Model 6.10.
Why neural texture compression is not texture upscaling
The two techniques can both use machine learning, but they solve different problems.
Neural Texture Compression vs Super Resolution
| Neural Texture Compression | Super Resolution | |
|---|---|---|
| Input | ||
| Goal | ||
| When it runs | ||
| Output |
Neural Texture Compression can therefore exist underneath DLSS, FSR, XeSS or native rendering. It changes how material data is stored and reconstructed, not the final display resolution.
The quality knob is bits per pixel
NTC is lossy compression. The amount of compressed information is controlled largely through the bits-per-pixel setting.
Higher bitrate gives the model more information and generally improves reconstruction quality. Lower bitrate improves compression but increases the risk of visible error.
Because multiple channels share the same representation, adding more material channels without increasing the bitrate can reduce the quality available to each channel.
Why correlated material channels are important
A neural representation becomes more valuable when several material channels describe related structure.
If albedo, normal and roughness all contain the same scratches, seams or fabric weave, the decoder can exploit shared spatial information.
If the channels are unrelated noise, there is less common structure to exploit and the compression problem becomes harder.
The Neural Texture Value Test
When is neural texture compression actually useful?
Why “8× smaller” needs context
NVIDIA's RTX Kit describes RTX Neural Texture Compression as offering up to 8× disk-memory improvement at similar visual fidelity to traditional block compression.
The phrase “up to” matters. Compression ratio depends on the material, number of channels, target bitrate, decoder configuration and quality threshold.
The same ratio also does not automatically describe VRAM savings. Inference on Load can start from a compact file and still expand into conventional GPU textures. Inference on Sample preserves the compact representation in GPU memory but spends more compute during shading.
Decoder size is another performance-quality trade-off
The NTC runtime uses a small multilayer perceptron to decode texture values.
NVIDIA's current library uses a configurable decoder architecture. Larger networks can improve compression quality but cost more to execute; smaller networks can run faster with some loss in reconstruction quality.
That gives engine developers another tuning dimension beyond texture resolution and bitrate.
Why this matters for future game installations
Modern games increasingly ship high-resolution material sets that affect download size as well as runtime memory.
Neural texture compression creates a new option: ship a compact learned representation and decide later whether to expand it on load, reconstruct it directly during shading or decode only requested tiles.
That means one compressed asset representation can participate in several different runtime memory strategies.
It also changes what 'texture memory' means
With traditional rendering, a texture-memory budget is mostly about texture formats, mip levels, resolution and residency.
With neural textures, developers may also budget latent data, decoder weights, inference buffers, transcoded caches and the compute needed to reconstruct requested values.
So the asset no longer has one simple fixed memory identity.
Cross-vendor support is more nuanced than the RTX name suggests
RTXNTC is an NVIDIA SDK, and compression itself currently requires an NVIDIA GPU according to the SDK requirements.
Runtime decompression is broader. NVIDIA documents functional paths on Shader Model 6 hardware and notes validation on NVIDIA, AMD and Intel GPUs, while advanced Cooperative Vector / Linear Algebra paths depend on API and driver support.
Performance and feature parity therefore should not be assumed across vendors merely because the basic decoder can run.
What would change this answer?
NTC is still beta. Runtime modes, decoder architectures, driver support and integration paths can change before a stable production release.
The biggest long-term change would be broad adoption of standardized neural-shader primitives across DirectX and Vulkan. That would make neural texture decoding less dependent on custom vendor-specific execution paths.
Limitations
This article describes the architecture and current public RTXNTC SDK behavior. NVIDIA's quoted compression claims are vendor-provided and should not be treated as guaranteed results for every material.
The current SDK is beta software, and some preview paths have documented driver and platform limitations.
Conclusion
RTX Neural Texture Compression is interesting because it changes a very old assumption: texture detail does not always have to exist in memory as conventional texels.
A material can instead be stored partly as a compact learned representation and reconstructed when needed.
That does not give free quality or free memory. It creates a new exchange: less storage, bandwidth and potentially VRAM in return for neural inference work.
The real innovation is not “AI makes textures sharper.” It is that part of a game's material data can become computation.
FAQ
RTX Neural Texture Compression in plain English
Is RTX Neural Texture Compression an upscaler?
Can NTC reduce VRAM usage?
What does the neural network store?
Does NTC decode the whole texture before rendering?
Is neural texture compression lossless?
Is RTXNTC production-ready?
Glossary
Key neural texture terms
- Neural Texture Compression
- A technique that stores texture information as compact latent data plus neural decoder weights instead of only conventional texel blocks.
- Latent data
- Compact learned features that the neural decoder uses to reconstruct texture values.
- Decoder
- A small neural network that converts latent features into reconstructed texture channels.
- Inference on Load
- Runtime mode that decodes the neural texture when an asset is loaded, usually into conventional texture formats.
- Inference on Sample
- Runtime mode that performs neural decoding directly during texture sampling so the compressed representation can remain resident.
- Inference on Feedback
- Runtime strategy that uses texture feedback to decode and cache only requested tiles.
- Texture Storage–Compute Exchange
- A Figure Rocks model describing the trade of texture storage, bandwidth and VRAM for additional GPU neural-inference work.
- Neural Texture Value Test
- A Figure Rocks workflow for deciding whether neural texture compression creates a net benefit for a particular material and target GPU.
Primary sources
NVIDIA Developer — RTX KitOfficial overview of RTX Neural Texture Compression and NVIDIA's published storage-reduction positioning.
NVIDIA RTXNTC — SDK READMEOfficial SDK documentation describing material-channel compression, decoder/latent representation, runtime modes, memory examples, system requirements and Cooperative Vector support.
NVIDIA RTXNTC — ReleasesOfficial release history, including v0.10.0 beta and DirectX 12 Linear Algebra inference support.
NVIDIA RTXNTC — Compression Settings and Image QualityOfficial documentation covering bitrate, channel interactions, quality measurement and lossy compression behavior.
NVIDIA — LibNTCOfficial runtime library documentation describing decoder configuration and the quality/performance trade-off of different neural-network sizes.
Related Articles
Windows Auto SR Is Not DLSS: How NPU Upscaling Works Without Game Integration
Windows Auto SR can upscale supported games without DLSS, FSR or XeSS integration. Instead of running the reconstruction model inside the game on the GPU, Windows uses the NPU to rebuild a higher-resolution image from a lower-resolution render.
Storage Streaming Stutter Fixes: When Assets Can’t Keep Up
Streaming stutter happens when new areas load: storage, decompression, or asset streaming limits. Use this fix order before you drop every graphics setting.
Storage and Streaming: Reduce Load Times Without Creating Stutter
Fast storage helps only when streaming behavior is stable. This guide explains how IO affects stutter and what to change first.
DLSS 5 Is Not Just Upscaling: What 3D-Guided Neural Rendering Actually Changes
DLSS 5 moves AI into a new part of the graphics pipeline. Instead of only reconstructing resolution or generating extra frames, 3D-Guided Neural Rendering uses the game engine’s own frame as the foundation and enhances lighting and material detail under developer control.
amiibo FAQ: The 20 Questions Everyone Asks (And the Straight Answers)
A no-fluff Amiibo FAQ: compatibility, scanning, regions, reprints, value, and collecting rules — answered clearly so beginners stop wasting money.
DirectStorage 1.4 Does Not Make Your SSD Decompress Games: What Zstd and GPU Decompression Actually Do
DirectStorage 1.4 adds Zstandard compression, GPU decompression and a new Game Asset Conditioning Library, but the SSD itself is still only one part of the loading pipeline. This guide explains what the SSD, DirectStorage, CPU, GPU and game engine each actually do.
Lowered Graphics Settings but FPS Didn't Improve? You're Probably Tuning the Wrong Bottleneck
You lower shadows, effects and resolution, but the FPS barely changes. This guide explains why graphics settings only help when they reduce the workload that is actually limiting the frame—and how to identify CPU, GPU, memory, streaming and frame-cap bottlenecks.
VRAM Usage Is Not VRAM Requirement: Why a Full Memory Meter Does Not Tell the Whole Story
Seeing 7.8 GB used on an 8 GB graphics card can look like proof that a game has run out of VRAM. It is not that simple. This guide explains VRAM capacity, residency budgets, working sets, shared memory and how to tell whether memory pressure is actually causing stutter.